AI Inference Tokens, Priced by the Million
Choose a model from our rate card, call one HTTPS endpoint and pay per million tokens. Input and output are metered separately, invoices itemise every request, and production runs in Thailand on power we partly generate ourselves.
Tokens, sold by the million
Our product is model inference output. It is priced per million tokens, delivered over an API and billed monthly, so the commercial terms are readable before you commit.
When you call our endpoint, a model runs on hardware we own, in a hall we built, on electricity we partly generate. What arrives back is a completion, and what appears on your invoice is a token count multiplied by a published unit price.
Spend follows usage. If your traffic doubles, your invoice roughly doubles; if it halves, you are not carrying capacity you committed to a year ago. Committed volume plans lower the unit price when your monthly range is predictable, and reserved capacity fixes the monthly fee entirely.
Input tokens and output tokens are metered separately, because they cost different amounts to produce. Failed and rate-limited requests are not billed. Every response carries its own token counts and billed amount, so any line on a monthly invoice can be traced back to a specific call.
Inference tokens
The product is model inference output, measured in tokens. You buy completed generations, priced per million tokens on the published rate card.
Per million tokens
Input tokens and output tokens are metered and priced separately, per model, per request. The unit price is on the rate card before you commit.
HTTPS API endpoint and key
A standard JSON endpoint with streaming support, an OpenAI-compatible surface, SDKs and an API key issued per environment.
Prepaid credits or monthly invoice
Pay-as-you-go runs on a prepaid balance; committed volume and reserved capacity are settled monthly in arrears with a token-level breakdown.
The tokens we sell, and what they cost
Every product below is sold by the million tokens, with input and output priced separately. Filter by the kind of workload you are building.
| Model | Tier | Context | Input / 1M | Output / 1M | Latency | Best for |
|---|---|---|---|---|---|---|
| TGP-Chat 32B | Standard | 32K | $0.35 | $0.90 | Fast | Customer support replies, product copy, summarisation, everyday assistant traffic. |
| TGP-Chat 8B Lite | Economy | 16K | $0.08 | $0.22 | Fastest | High-volume classification, routing, short rewrites and form assistance. |
| TGP-Long 128K | Standard | 128K | $0.70 | $1.60 | Standard | Contract review, multi-document Q&A, long transcripts and report generation. |
| TGP-Long 512K | Premium | 512K | $1.40 | $3.20 | Standard | Whole-repository or whole-case-file reasoning where retrieval is not enough. |
| TGP-Code 32B | Standard | 64K | $0.45 | $1.10 | Fast | Code completion, refactoring, test generation and review comments. |
| TGP-Agent 70B | Premium | 128K | $1.10 | $2.60 | Standard | Multi-step tool calling, planning loops and autonomous agent backends. |
| TGP-SEA 32B | Standard | 32K | $0.40 | $0.95 | Fast | Thai, Vietnamese, Bahasa, Filipino and Burmese conversation and translation. |
| TGP-Thai Native | Specialist | 32K | $0.38 | $0.88 | Fast | Thai-language customer service with correct register, particles and formal tone. |
| TGP-Vision 12B | Standard | 32K | $0.60 | $1.30 | Standard | Invoice and label reading, photo moderation, diagram and screenshot questions. |
| TGP-Batch 32B | Economy | 32K | $0.18 | $0.45 | Within 24h | Offline tagging, dataset labelling, bulk translation and archive processing. |
| TGP-Batch Long | Economy | 128K | $0.35 | $0.80 | Within 24h | Large-scale document summarisation where response time is not critical. |
Reference prices for planning discussion, in USD and exclusive of applicable tax. Confirmed unit prices, rate limits and settlement terms are issued in the written quotation.
Request the full rate cardThree ways to buy tokens
The product is the same. What changes is how much you commit, how the unit price is set and how the invoice is raised.
Pay-as-you-go
No commitmentRate card price
per million tokens
Prototypes, pilots and traffic that is still unpredictable.
- Prepaid credit balance, spend stops when credits run out
- Full model catalogue available from day one
- No minimum monthly volume
- Monthly invoice with per-model token breakdown
- Standard rate limits, upgradeable on request
Prepaid credits, billed at rate card price
Get this pricingCommitted Volume
Up to 35% below rate card
on committed monthly tokens
Production applications with a known monthly token range.
- Discounted unit price against a committed monthly token volume
- Overage billed at standard rate card price, no service interruption
- Higher concurrency and rate limits included
- Priority queue during regional peak hours
- Quarterly usage review and commitment resizing
Monthly commitment, settled in arrears
Get this pricingReserved Capacity
DedicatedFixed monthly fee
tokens inside capacity uncapped
Teams that need predictable latency, isolation and cost ceiling.
- GPU capacity reserved for your workloads only
- No per-token metering inside the reserved envelope
- Custom or self-supplied model deployment supported
- Private endpoint, VPC peering or leased line options
- Named technical contact and change window
Fixed monthly fee, capacity reviewed quarterly
Get this pricingHow metering works
- Input and output tokens are metered and priced separately on every request.
- Failed, rejected and rate-limited requests are not billed.
- Cached prompt prefixes are billed at the discounted cached-input rate where the model supports it.
- Invoices itemise tokens by model, by day and by API key, with the energy source of the producing site.
- Prices are quoted in USD, exclusive of Thai VAT where applicable; FX and tax treatment are stated in the contract.
One endpoint, one API key
Tokens are delivered over a standard HTTPS API. For most teams already calling a hosted model, integration is a base URL and a key change.
Endpoint and authentication
A single HTTPS base URL with bearer-key authentication. Keys are issued per environment, can be scoped to a model group and revoked without affecting other keys.
OpenAI-compatible surface
Chat completion requests follow the widely used schema, so most existing client code only needs a base URL and key change. Native endpoints are available for batch and vision products.
Streaming and structured output
Server-sent events stream first tokens immediately; JSON mode and tool calling are supported on agent-tier models for multi-step workflows.
Rate limits and concurrency
Every plan carries a documented requests-per-minute and concurrent-request ceiling. Limits are raised on committed volume and reserved capacity rather than negotiated case by case.
Private connectivity
VPC peering, cross-connect or leased line into the producing site for traffic that should not traverse the public internet.
Your own models
Self-supplied or fine-tuned weights can be hosted on reserved capacity and sold back to you as tokens under the same metering and billing format.
Usage dashboard and webhooks
Live token consumption by key, model and day; budget thresholds and low-balance alerts pushed to your own webhook or email.
Sandbox and trial credits
Trial credits are issued against a sandbox key so integration and latency testing happen before any commercial commitment.
curl https://api.thaigoodproducts.co.th/v1/chat/completions \
  -H "Authorization: Bearer $TGP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "tgp-chat-32b",
    "stream": true,
    "messages": [
      { "role": "user", "content": "Summarise this support ticket in Thai" }
    ]
  }'

// response.usage
// {
//   "prompt_tokens": 1284,
//   "completion_tokens": 312,
//   "total_tokens": 1596,
//   "billed_input_usd": 0.000449,
//   "billed_output_usd": 0.000281
// }
What every response returns
- Input and output token counts for that request
- The USD amount billed, split between input and output
- Model and site identifier used for production
- Request id, so any billing line can be traced back
What we commit to in writing
These are the terms a token purchase is actually judged on. Each one is stated per contract, with the measurement method described alongside it.
Availability and latency figures are contractual targets measured and reported monthly. They are service objectives, not a guarantee of business outcome, and the applicable values for your workload are the ones written into your agreement.
From volume estimate to first invoice
Five steps from first estimate to first invoice. Testing happens on trial credits before any price is agreed.
Estimate your token volume
Share the use case, average prompt and response length, and expected monthly requests. We return an estimated token count and a model shortlist.
1-2 working days
Trial credits and testing
A sandbox key with trial credits is issued so you can test quality, latency and streaming against your own traffic before pricing is agreed.
Same day on request
Quotation and contract
Unit prices per million tokens, commitment level, settlement cycle, rate limits, SLA targets and data terms are fixed in writing.
3-5 working days
Production keys and go-live
Production keys, rate limits and webhook endpoints are provisioned; we support integration testing and cutover from your current provider.
1-3 working days
Metering and monthly billing
Usage is metered per request and reported by model, key and day. Invoices arrive monthly with the token breakdown and energy source.
Ongoing
What customers spend tokens on
Token consumption structure differs by workload, and so does the plan that makes sense. These are the six we quote most often.
Customer support assistants
Short prompts, high volume, latency sensitive. Typically output-heavy on economy and standard tiers.
Typical plan · Committed Volume
Content and marketing generation
Long outputs with several revision rounds. Output tokens dominate the bill, so tier choice matters more than context size.
Typical plan · Pay-as-you-go
Code assistants and agents
Multi-step tool calling with large context carried between turns. Input tokens accumulate quickly across a session.
Typical plan · Reserved Capacity
Document and contract understanding
Very long inputs, moderate outputs. Long-context products with cached prompt prefixes reduce repeat-read cost.
Typical plan · Committed Volume
ASEAN multilingual localisation
Thai, Vietnamese, Bahasa and Filipino traffic where a native-tuned model avoids costly post-editing.
Typical plan · Committed Volume
Offline batch processing
Dataset labelling, bulk translation and archive summarisation where a 24-hour window is acceptable.
Typical plan · Batch rate card
Supply figures are reference values for planning discussion. Committed throughput, rate limits and unit prices are issued per contract in the written quotation.
The price is set by what we own upstream
You buy tokens. The reason the unit price can hold is that the inputs behind them — power, hall, cooling and the GPU fleet — are owned and operated by one party.
Power we generate ourselves
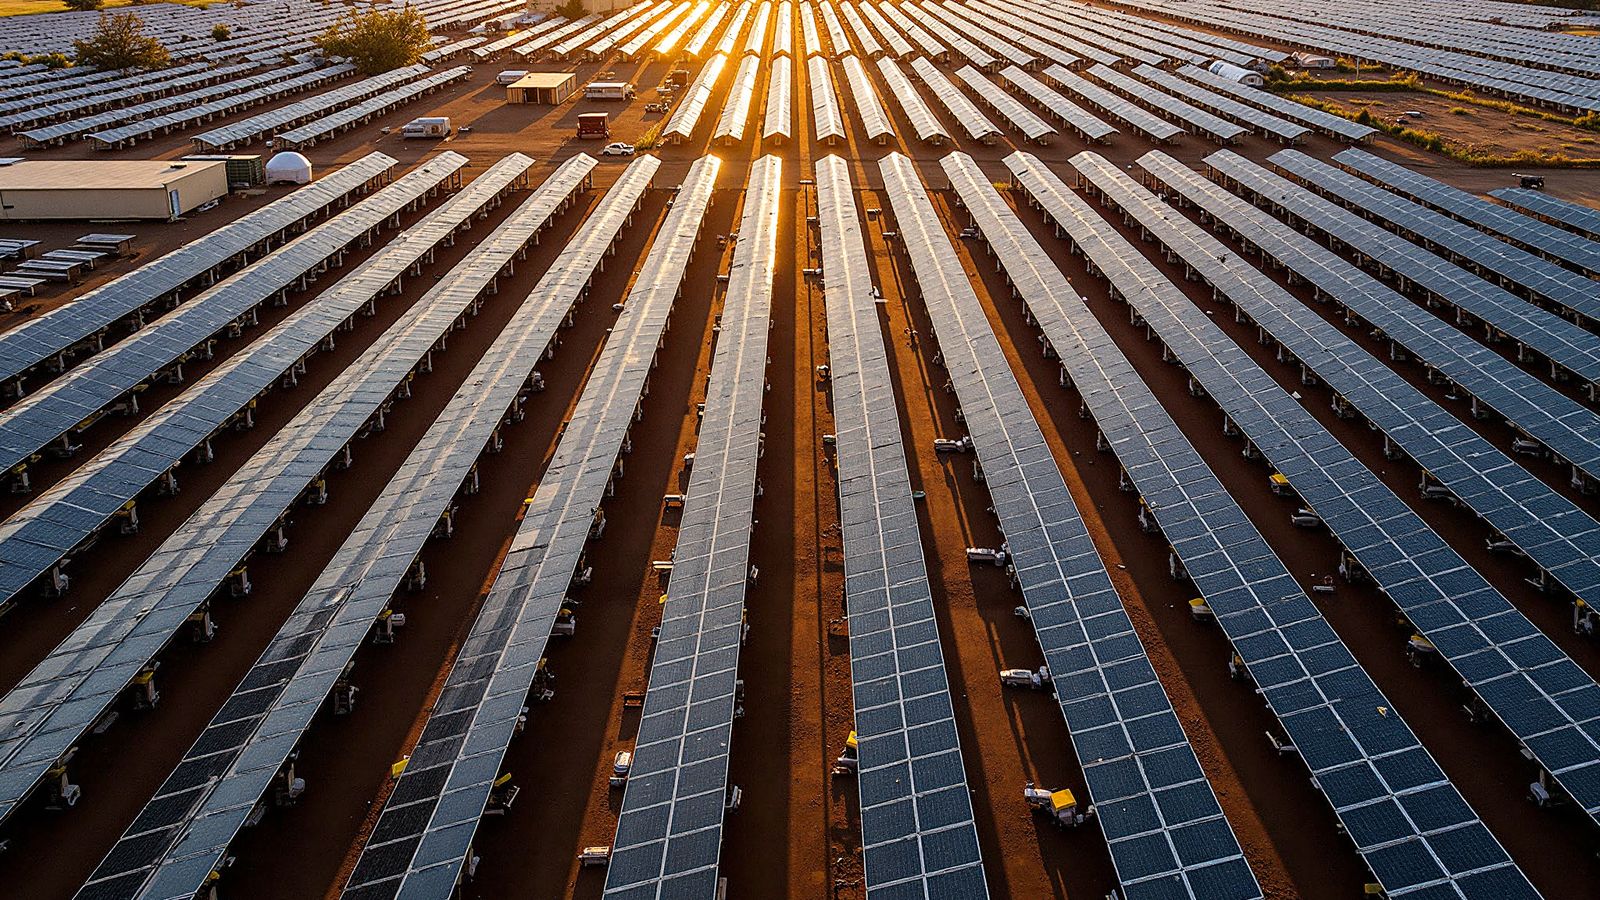
Electricity is the largest single input in a produced token. Our own photovoltaic projects supply part of the load, so the energy component of the unit price is sourced rather than resold.
No reseller layers
The hall, the power chain, the cooling plant and the GPU fleet are operated by one party. Margins that would otherwise be stacked by a broker, a facility operator and a cloud reseller stay out of the price.
Utilisation engineered, not hoped for
Request patterns are profiled, inference is batched where latency allows, and capacity is resized against measured demand instead of a forecast made at signing.
Dual metering makes price traceable
Energy is metered per hall and tokens per request. When a unit price is quoted, the assumptions behind it can be shown and challenged rather than accepted on trust.
Part of the electricity is generated, not purchased
We develop photovoltaic projects in parallel with token production. Generation and consumption are metered separately, so a customer that reports energy sourcing to its own stakeholders can be offered a documented solar-backed option rather than a certificate bought after the fact.
What buyers ask before their first invoice
Every request is metered for input tokens and output tokens separately, multiplied by the unit price of the model you called. Prices are quoted per million tokens. Pay-as-you-go draws down a prepaid balance; committed volume and reserved capacity are invoiced monthly in arrears.
Get token pricing and trial credits
Tell us the use case, average prompt and response length, and expected monthly requests. We will return an estimated token volume, a model shortlist and a written quotation.